How does Book Search Work?
This document is aimed at the following audiences:
- Employer/Recruters/Interviewer
- Tech Enthusiast
Stack:
- Backend: Python, Flask, SQLite, Pandas, Jinja, Google Cloud Run
- Frontend: JavaScript, HTML, CSS
Components:
- Search Engine:
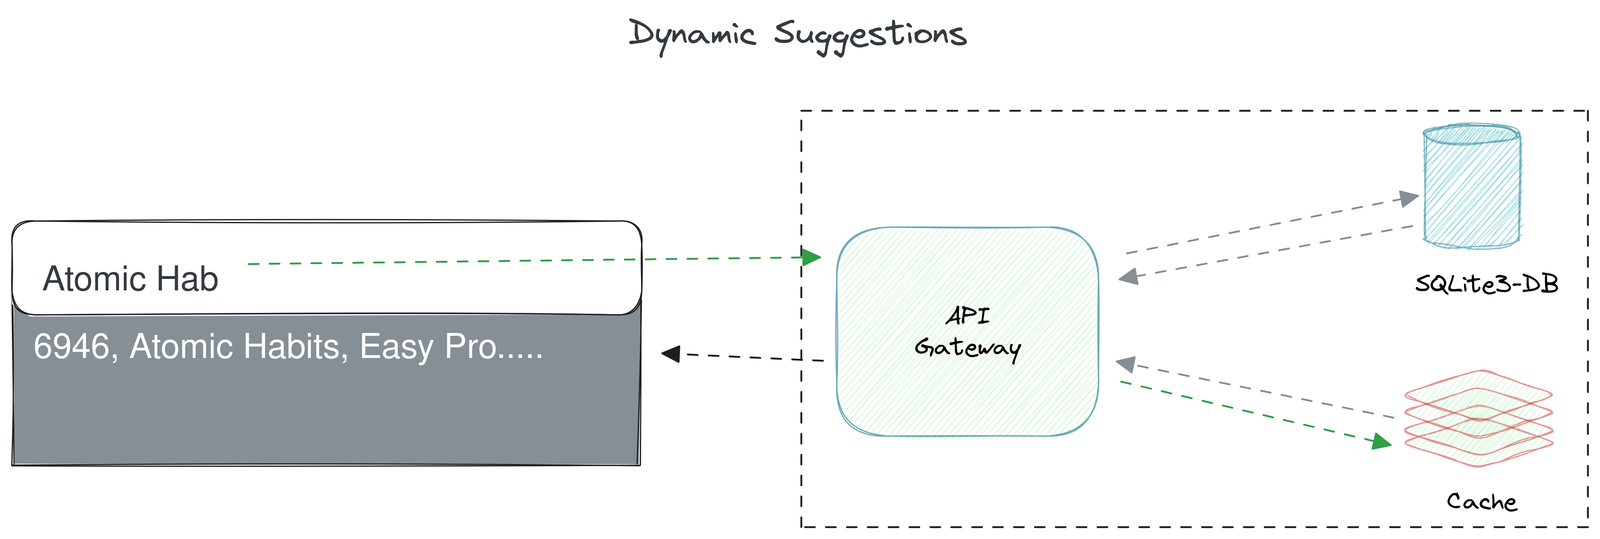
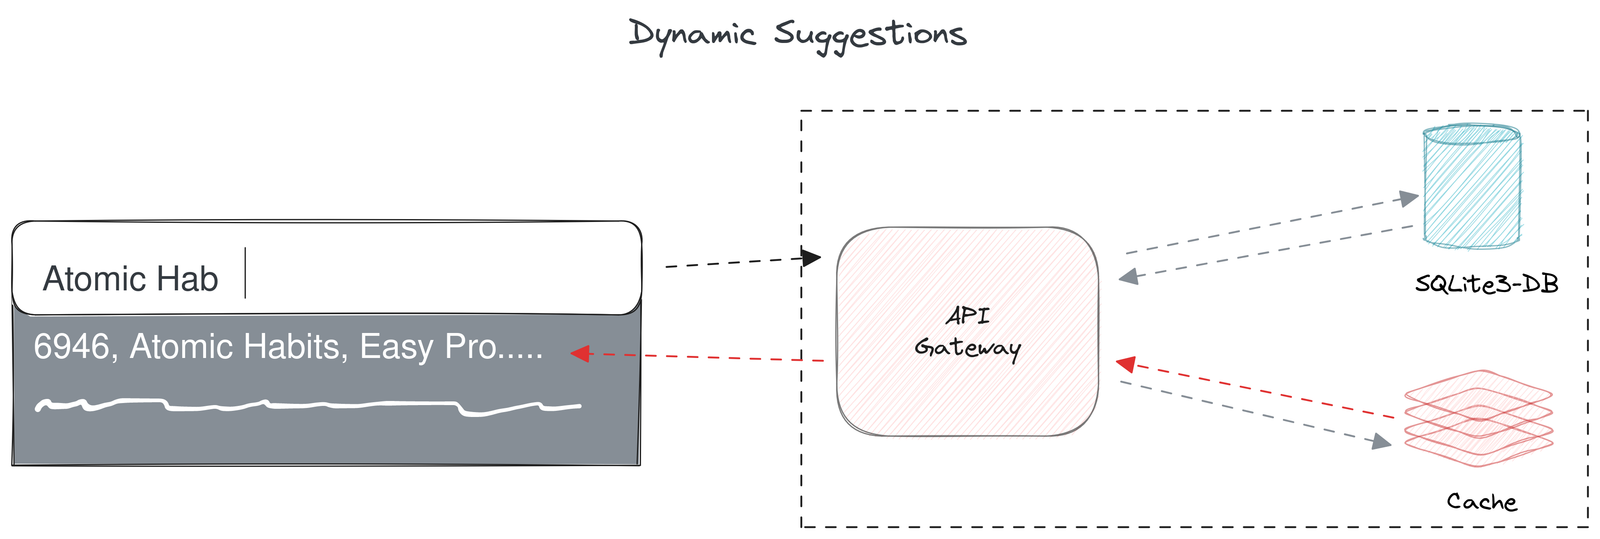
- Dyanamic Search Suggestions.
- Flask Application in Backend:
- SQLite3 Database.
- Pandas/Numpy array for search Suggestions.
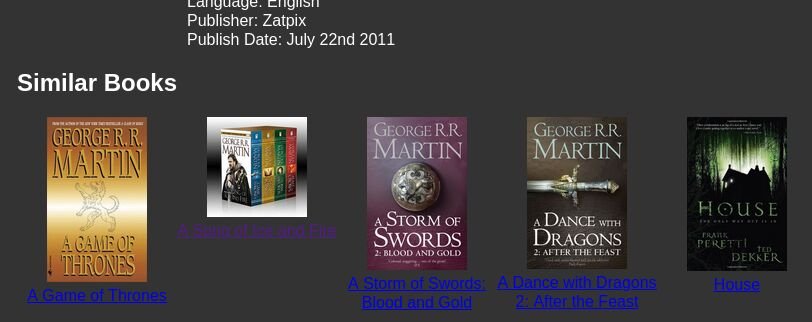
- Similar Book Recommendations:
- Cosine Similarity Logic.
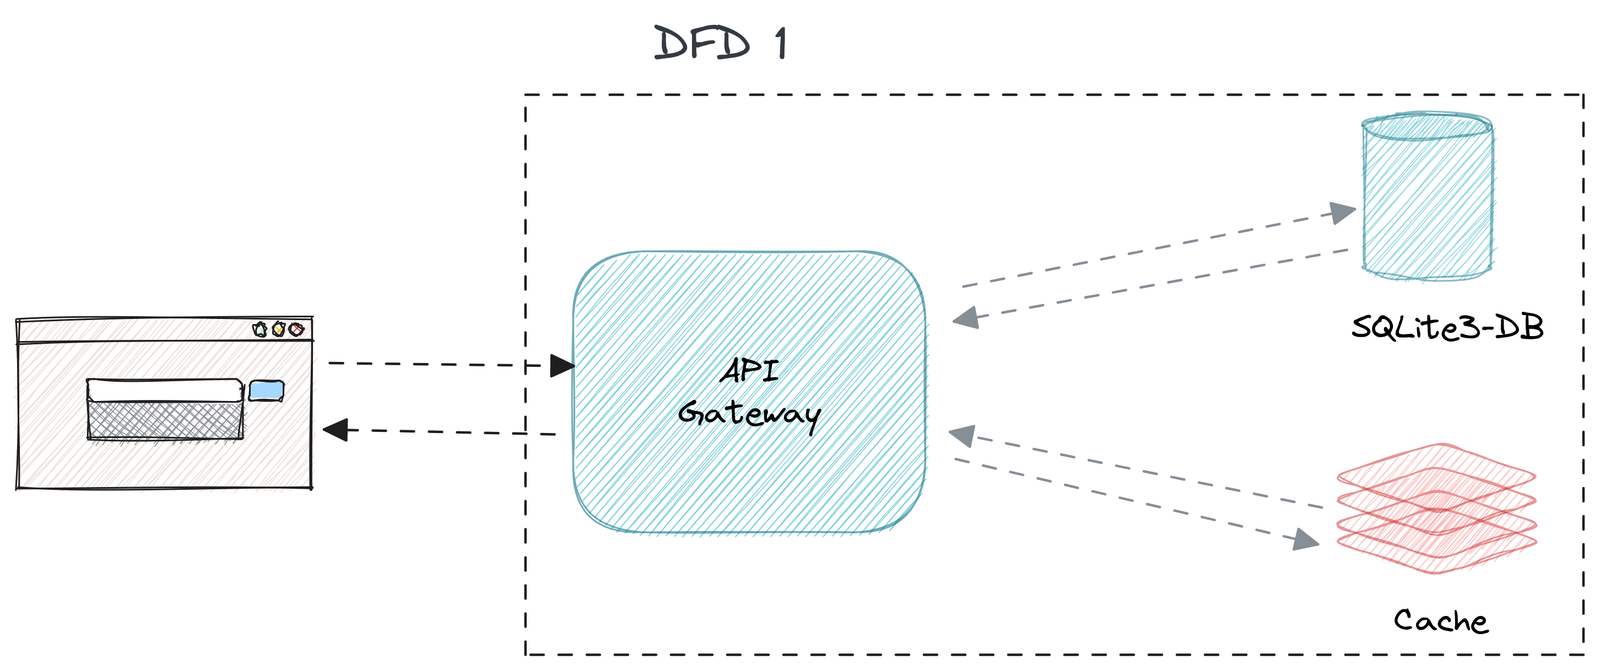
High Level Overview of Application.
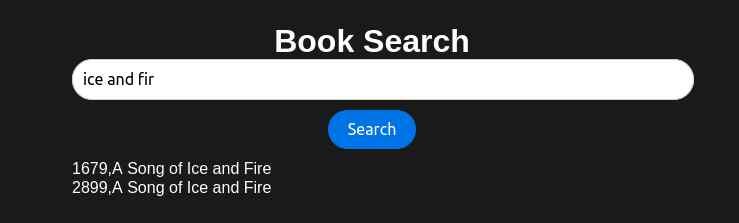
Search: Write desired text. Post requests to backend. Python function returns subarray of numpy array of book titles with indexes as search suggestions.
Get Book: Get request with search text as body to backend. Backend returns json response of book data by querying to SQLite3 DB.
Database.
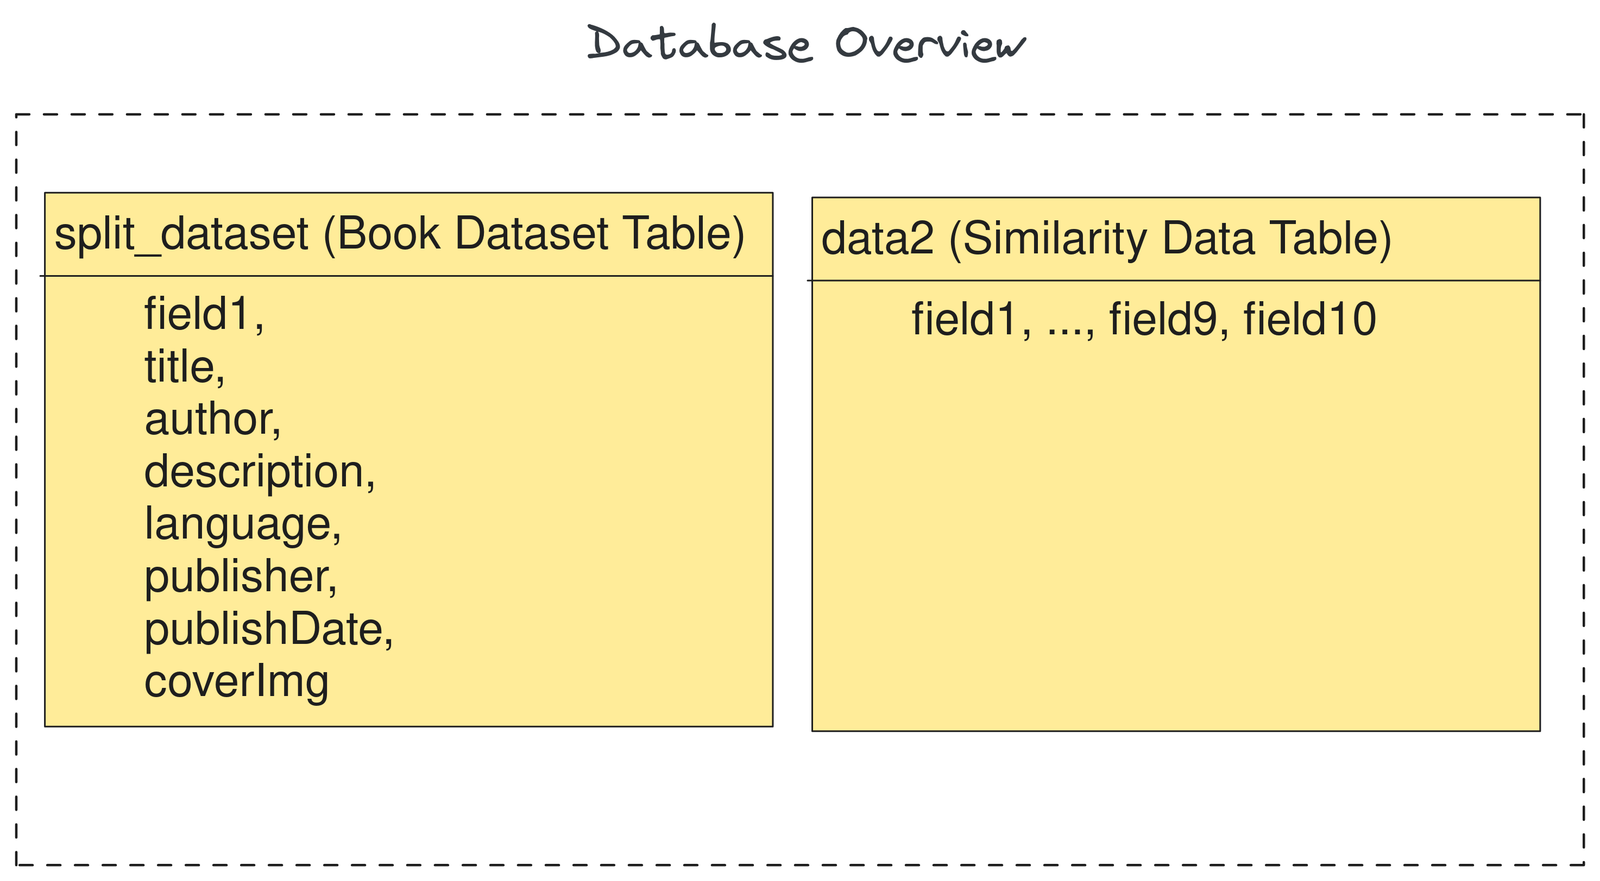
Database consist of two tables: Similarity, Dataset
Database Fields:
Similarity: field1 to field9, field10
Dataset: field1, title, author, description, language, publisher, publishDate, coverImg
Dataset Table stores information about 10,000 most favourite books of goodreads.
Similarity Table stores cosine similarity of 10 most similar books for each book
Cosine Similarity.
I am assuming that reader knows about cosine similarity. For more information checkout blog that wrote few weeks ago.
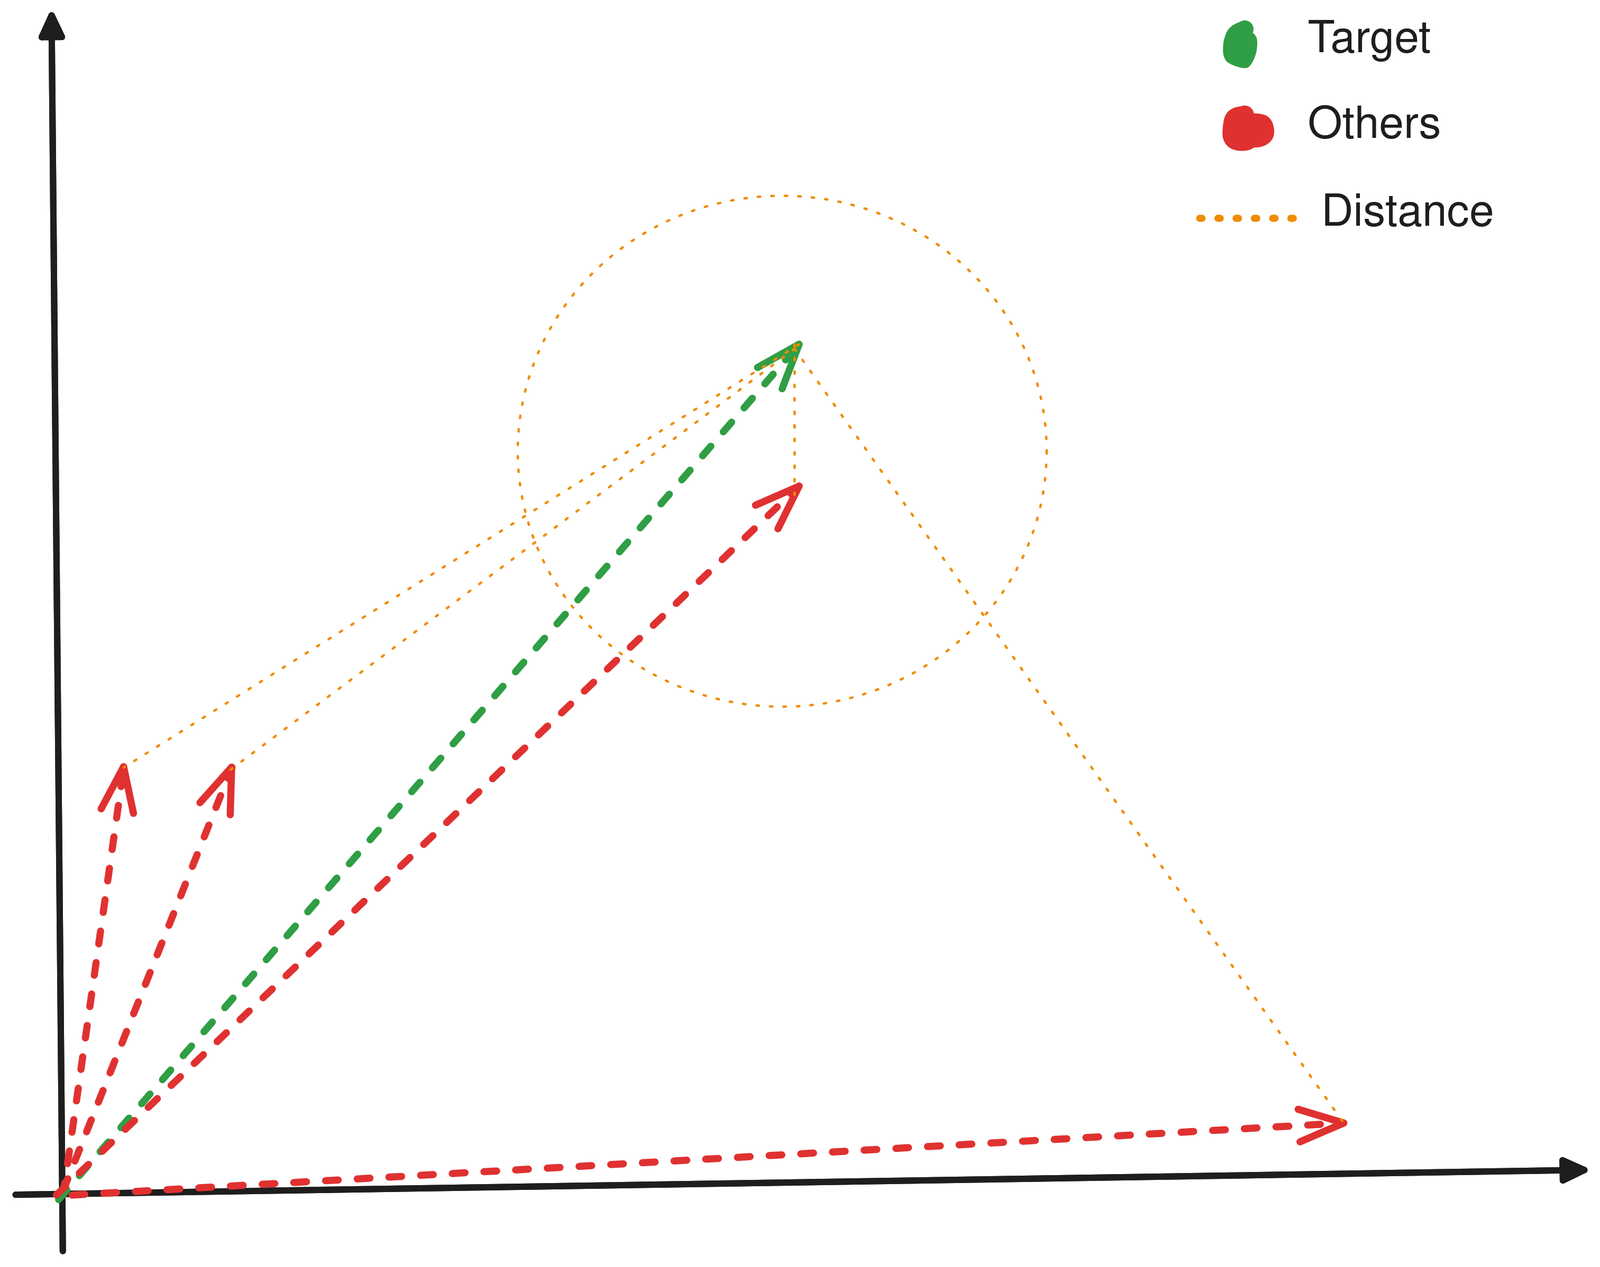
Let's assume on a 2d plain, vectors represents a positions. each position on this plain is a representation of a type of book. To find out a book similar to the target type naturally we will look at a vector that is closest to the target vector. This is a cosine similarity in nutshell.